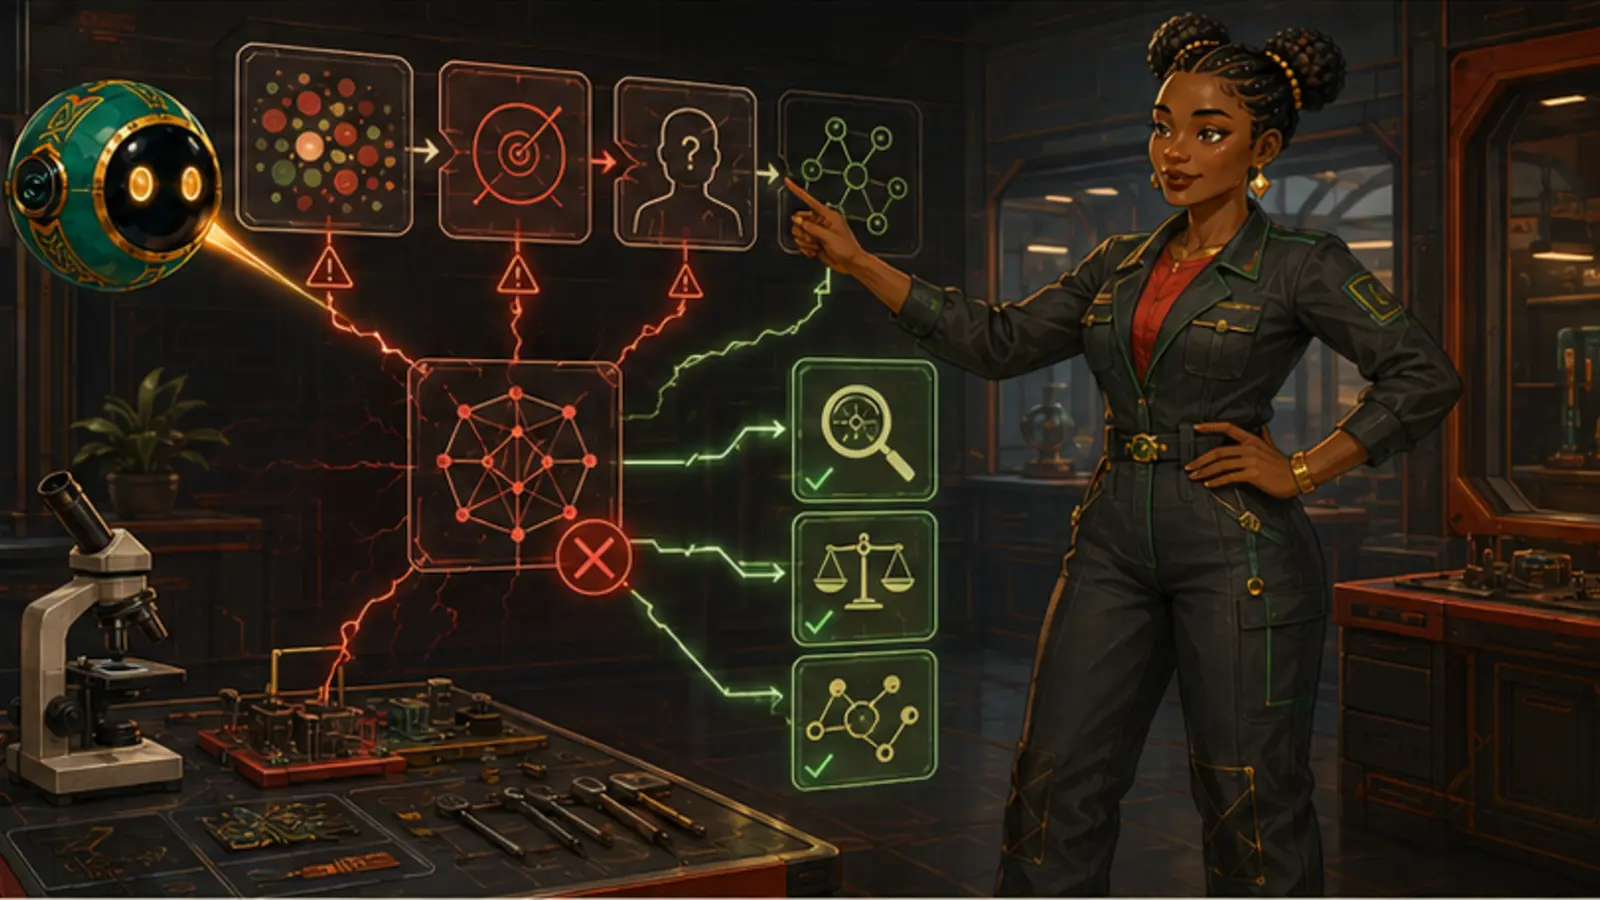
AI errors come from five places: the training data, what the system was optimised for, the context you gave it, the limits of the model itself, and the interface that hid something from you.
Do now: Take one wrong answer you have received and work out which of the five caused it.
Fluency is produced by the model. Accuracy has to be produced by you.People who treat every AI mistake as random bad luck cannot prevent any of them. People who can name the cause can usually stop that class of error happening again, which is the difference between using these tools carefully and using them hopefully.
Five causes, five different fixes
Data. The system learned from material that was incomplete, out of date, skewed toward some places and languages, or simply wrong. This is why answers about small towns, minority languages and recent events degrade fastest, and why the confidence does not degrade with them.
Objective. Models are trained to produce responses people rate well. Helpful and correct usually overlap, but where they do not, the training pressure is toward the answer that satisfies. This is why a model will often produce an answer rather than say it does not know, and why flattery is a known failure mode.
Context. You gave it an ambiguous instruction, left out the constraint that mattered, or supplied a document it misread. A surprising share of 'AI errors' are actually briefing errors, and those are the cheapest ones to fix because they are entirely on your side of the exchange.
Model limits. Long chains of reasoning drift. Arithmetic on unfamiliar numbers goes astray. Precise recall of specifics — a page number, a figure, a citation — is exactly where a pattern-based system is weakest, because a plausible specific is as easy to produce as a true one.
Interface. The tool silently truncated your document, ignored an attachment, used an older version, or applied a system instruction you never saw. This one is invisible by definition, which is why unexplained wrongness is worth investigating rather than re-prompting.
Prevention only works when it matches the cause. Re-prompting fixes a context error and does nothing for a data error.
Why the confidence never changes
A person who is unsure hesitates, hedges, or says so. That signal is genuinely useful, and we rely on it constantly without noticing. A language model produces the same fluent register whether it is on firm ground or inventing, because the fluency comes from the same process either way.
So you cannot read reliability off the surface of the answer. You have to know, in advance, which kinds of question this system is likely to be good at. Explaining a stable concept: reliable. Recalling a specific recent figure: unreliable. Structuring material you supplied: reliable. Naming a source: unreliable until opened.
You can ask for uncertainty, and it helps a little — asking what would change the answer, or which parts are least supported, often surfaces something real. But treat that as a prompt for your own checking, not as a measurement.
Build an error taxonomy for your own work
Keep a short log of failures for a fortnight: what you asked, what came back, what was wrong, and which of the five causes it was. Ten entries is enough to see your own pattern, and your pattern will be specific to your work.
Most people find one cause dominates. Someone working with local information will see data errors constantly. Someone giving fast, short instructions will see context errors. Someone asking for figures will see model-limit errors. Knowing which one is yours tells you where to spend your checking effort, rather than checking everything equally and therefore checking nothing well.
You cannot check everything. An error taxonomy tells you what to check first.